Speeding up Inference
See also
This page focuses on backend-level optimizations (ONNX, OpenVINO, model quantization). For complementary techniques that reduce storage and search cost at the embedding level, see the Binary and Scalar Embedding Quantization for Significantly Faster & Cheaper Retrieval blogpost (post-training compression of output vectors), the 🪆 Introduction to Matryoshka Embedding Models blogpost (truncatable embeddings), and the Train 400x faster Static Embedding Models blogpost (attention-free CPU-friendly models).
Sentence Transformers supports 3 backends for computing embeddings, each with its own optimizations for speeding up inference:
PyTorch
The PyTorch backend is the default backend for Sentence Transformers. If you don’t specify a device, it will use the strongest available option across “cuda”, “mps”, and “cpu”. Its default usage looks like this:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2")

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
If you’re using a GPU, then you can use the following options to speed up your inference:
Float32 (fp32, full precision) is the default floating-point format in torch, whereas float16 (fp16, half precision) is a reduced-precision floating-point format that can speed up inference on GPUs at a minimal loss of model accuracy. To use it, you can specify the torch_dtype during initialization or call model.half() on the initialized model:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", model_kwargs={"torch_dtype": "float16"})
# or: model.half()

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
Bfloat16 (bf16) is similar to fp16, but preserves more of the original accuracy of fp32. To use it, you can specify the torch_dtype during initialization or call model.bfloat16() on the initialized model:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", model_kwargs={"torch_dtype": "bfloat16"})
# or: model.bfloat16()

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
Flash Attention is an efficient attention implementation that can significantly speed up inference on GPUs. When flash attention with variable-length support is available, Sentence Transformers automatically skips padding for text-only inputs by concatenating them into a single sequence. This eliminates the overhead of padding shorter texts to the longest text in the batch, which is especially beneficial when input lengths vary widely.
To use flash attention, specify attn_implementation="flash_attention_2" in model_kwargs. Flash attention can be installed
via pip install kernels, which provides flash attention support without needing the flash-attn package, or alternatively
via pip install flash-attn:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    model_kwargs={"attn_implementation": "flash_attention_2", "torch_dtype": "bfloat16"},
)

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
Note
Automatic input unpadding requires transformers >= 5.0.0 and is enabled by default when flash attention
with variable-length support is installed and compatible with the model architecture. You can control this
via unpad_inputs on the underlying
Transformer module:
model[0].unpad_inputs = False   # Force padding (e.g. for architectures that don't support unpadded inputs)
model[0].unpad_inputs = True    # Explicitly request unpadding
model[0].unpad_inputs = None    # Auto-detect (default)
The following benchmark compares throughput and VRAM usage across three attention configurations using BAAI/bge-base-en-v1.5, averaged across batch sizes. Four datasets with varying text lengths are tested.
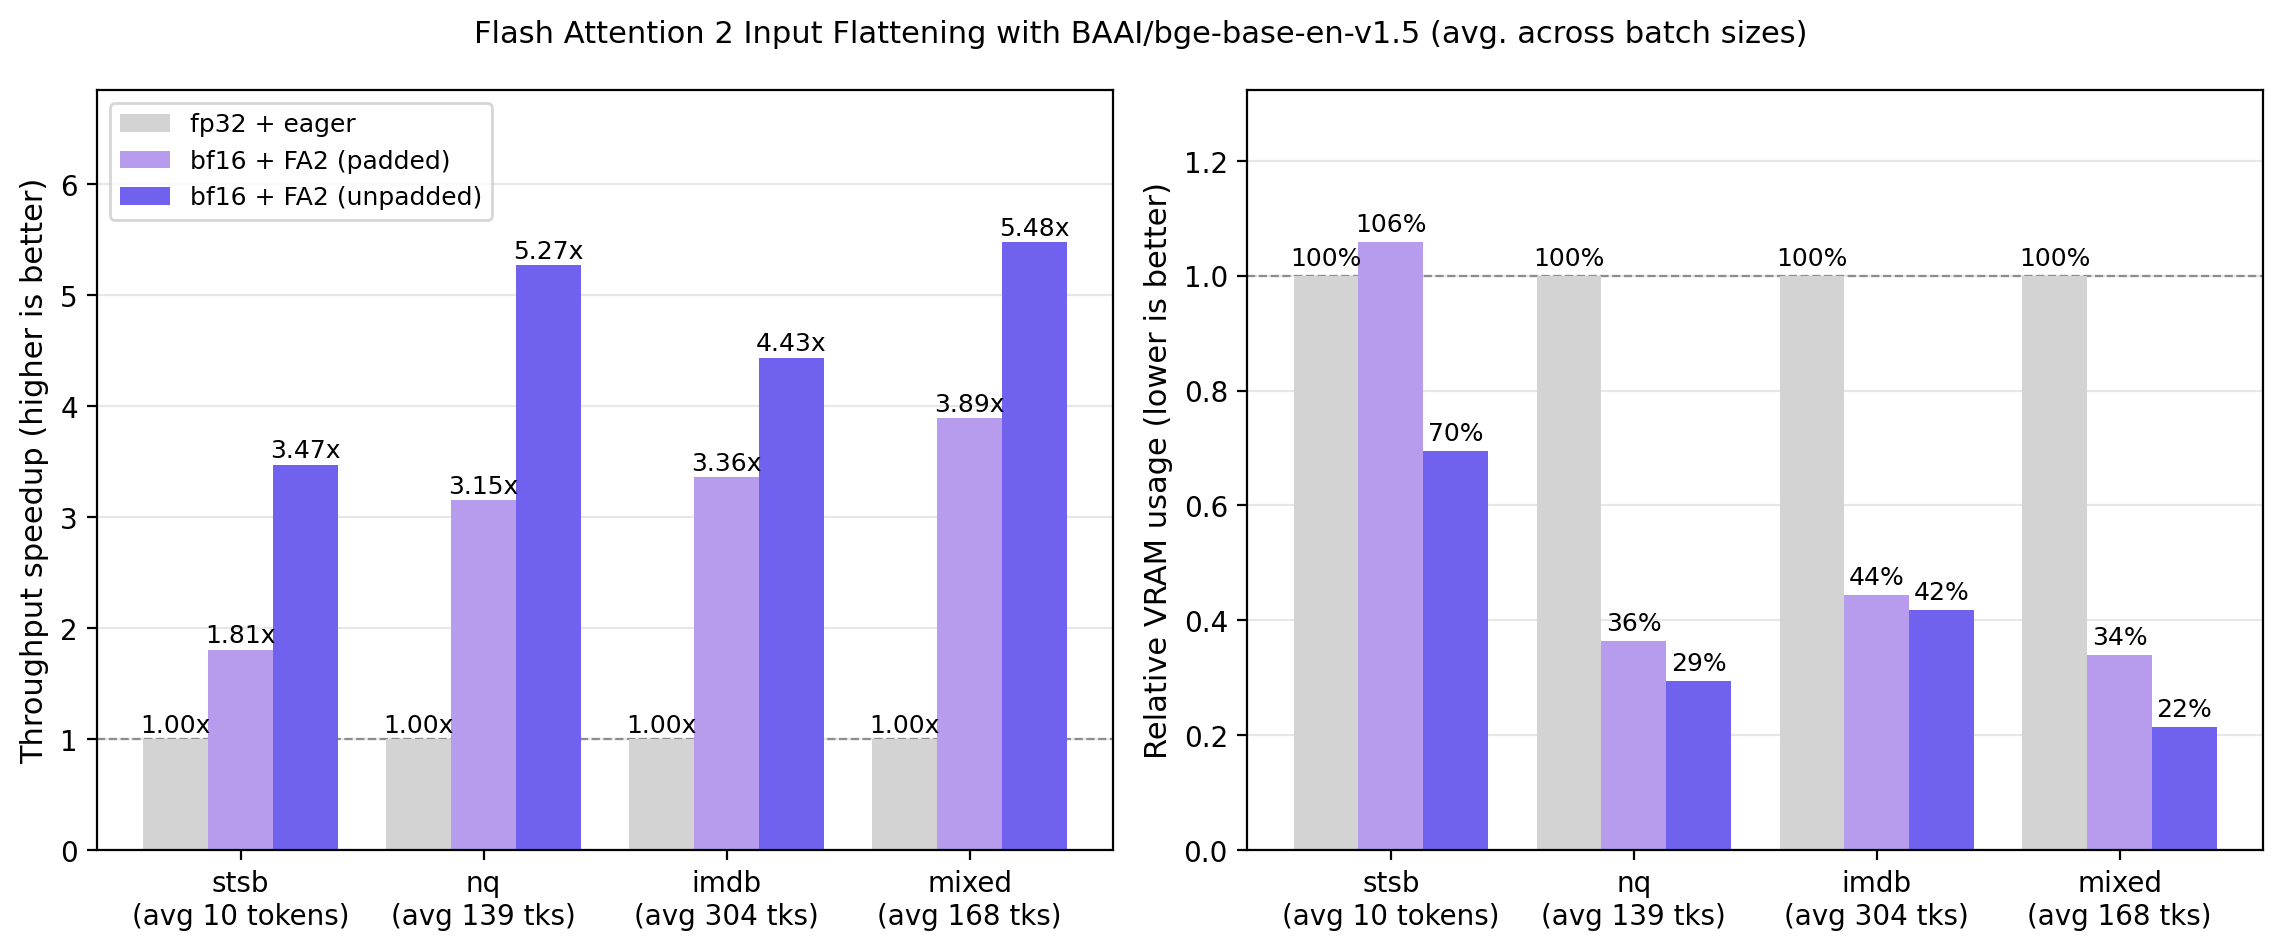
Input flattening improves throughput and reduces VRAM use in this benchmark, with the largest gains on the mixed dataset, where input lengths range from 10 to 500 tokens. This makes it particularly useful for batches of texts with varying lengths, although the benefit depends on the model and batch size.
The backend benchmark below also shows the benefit of combining half precision with Flash Attention and input unpadding: FP16 with this setup achieves the highest median speedup across the tested models (3.87x over FP32), without reducing average task quality.
Input flattening also speeds up training. When training with a gradient-cached loss such as
CachedMultipleNegativesRankingLoss, you can additionally set
mini_batch_num_tokens instead of mini_batch_size. Mini-batches are then packed by total token count
rather than by sequence count, so every mini-batch performs a similar amount of work and uses a similar,
predictable amount of memory, regardless of how sequence lengths are distributed within the batch. This can
substantially increase training throughput on datasets with varying text lengths:
from sentence_transformers import SentenceTransformer, losses

model = SentenceTransformer(
    "answerdotai/ModernBERT-base",
    model_kwargs={"attn_implementation": "flash_attention_2", "torch_dtype": "bfloat16"},
)
loss = losses.CachedMultipleNegativesRankingLoss(model, mini_batch_num_tokens=32768)
Prefer the smallest budget that saturates your GPU: throughput plateaus beyond that point, and budgets that push peak memory close to the card’s limit gain little and can silently slow training down when the driver spills to system RAM instead of erroring.
See also
The Transformers Attention Interface documentation
for a full overview of available attn_implementation options, including "flash_attention_2",
"flash_attention_3", "sdpa", and more.
model.compile() wraps the model’s forward pass with
torch.compile(). Whether it helps depends strongly on the model and hardware: the benefit grows with model
size, and very small models on a fast GPU can see little gain or even a slight slowdown, since their inference is
dominated by tokenization and Python overhead. Always measure on your own model, hardware, and inputs. It composes
with the fp16/bf16 options above.
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", model_kwargs={"torch_dtype": "bfloat16"})
model.compile(dynamic=True)

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
dynamic=True enables dynamic shapes so a compiled graph can handle variable sequence lengths, reducing
recompilation when your inputs vary in length. For the largest speedup, use mode="reduce-overhead" instead:
it applies CUDA graphs to remove the per-kernel launch overhead that dominates batch-size-1 inference.
model.compile(mode="reduce-overhead")
However, CUDA graphs capture one graph per input shape, so they need stable shapes. Pad every input to a fixed
length near your typical length by passing padding="max_length" through processing_kwargs when encoding:
embeddings = model.encode(sentences, processing_kwargs={"text": {"padding": "max_length", "max_length": 256}})
max_length sets the fixed length that shorter inputs are padded up to and longer inputs are truncated down to.
It is optional and defaults to the tokenizer’s model_max_length.
Padding up to a large model_max_length (for example 8192) makes every call process the full length and is slower
than not compiling at all. CUDA graphs also reuse output buffers, so clone anything you keep across calls (the
default convert_to_numpy=True already copies off the GPU and is safe). Compilation is lazy, so warm the model
up on representative inputs before benchmarking or serving.
Note
When running a Sentence Transformers model alongside a generative LLM on the same GPU, keep an eye on VRAM usage and generation latency, as the two can contend for memory and compute. For latency-sensitive local setups, moving small embedding models to the CPU can help (e.g. SentenceTransformer(..., device="cpu") or model.encode(..., device="cpu")).
ONNX
ONNX can be used to speed up inference by converting the model to ONNX format and using ONNX Runtime to run the model. To use the ONNX backend, you must install Sentence Transformers with the onnx or onnx-gpu extra for CPU or GPU acceleration, respectively:
pip install sentence-transformers[onnx-gpu]
# or
pip install sentence-transformers[onnx]
To convert a model to ONNX format, you can use the following code:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="onnx")

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
If the model path or repository already contains a model in ONNX format, Sentence Transformers will automatically use it. Otherwise, it will convert the model to the ONNX format.
Note
If you wish to use the ONNX model outside of Sentence Transformers, you’ll need to perform pooling and/or normalization yourself. The ONNX export only converts the Transformer component, which outputs token embeddings, not sentence embeddings. To get sentence embeddings, you’ll need to apply the appropriate pooling strategy (like mean pooling) and any normalization that the original model uses.
All keyword arguments passed via model_kwargs will be passed on to ORTModel.from_pretrained. Some notable arguments include:
provider: ONNX Runtime provider to use for loading the model, e.g."CPUExecutionProvider". See https://onnxruntime.ai/docs/execution-providers/ for possible providers. If not specified, the strongest provider (E.g."CUDAExecutionProvider") will be used.file_name: The name of the ONNX file to load. If not specified, will default to"model.onnx"or otherwise"onnx/model.onnx". This argument is useful for specifying optimized or quantized models.export: A boolean flag specifying whether the model will be exported. If not provided,exportwill be set toTrueif the model repository or directory does not already contain an ONNX model.session_options: Anonnxruntime.SessionOptionsinstance for configuring ONNX Runtime. For example, adjustintra_op_num_threadsto tune CPU inference performance for your hardware and workload.
Tip
It’s heavily recommended to save the exported model to prevent having to re-export it every time you run your code. You can do this by calling model.save_pretrained() if your model was local:
model = SentenceTransformer("path/to/my/model", backend="onnx")
model.save_pretrained("path/to/my/model")
or with model.push_to_hub() if your model was from the Hugging Face Hub:
model = SentenceTransformer("intfloat/multilingual-e5-small", backend="onnx")
model.push_to_hub("intfloat/multilingual-e5-small", create_pr=True)
Optimizing ONNX Models
ONNX models can be optimized using Optimum, allowing for speedups on CPUs and GPUs alike. To do this, you can use the export_optimized_onnx_model() function, which saves the optimized in a directory or model repository that you specify. It expects:
model: a Sentence Transformer, Sparse Encoder, or Cross Encoder model loaded with the ONNX backend.optimization_config:"O1","O2","O3", or"O4"representing optimization levels fromAutoOptimizationConfig, or anOptimizationConfiginstance.model_name_or_path: a path to save the optimized model file, or the repository name if you want to push it to the Hugging Face Hub.push_to_hub: (Optional) a boolean to push the optimized model to the Hugging Face Hub.create_pr: (Optional) a boolean to create a pull request when pushing to the Hugging Face Hub. Useful when you don’t have write access to the repository.file_suffix: (Optional) a string to append to the model name when saving it. If not specified, the optimization level name string will be used, or just"optimized"if the optimization config was not just a string optimization level.
See this example for exporting a model with optimization level 3 (basic and extended general optimizations, transformers-specific fusions, fast Gelu approximation):
Only optimize once:
from sentence_transformers import SentenceTransformer, export_optimized_onnx_model

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="onnx")
export_optimized_onnx_model(
    model=model,
    optimization_config="O3",
    model_name_or_path="sentence-transformers/all-MiniLM-L6-v2",
    push_to_hub=True,
    create_pr=True,
)
Before the pull request gets merged:
from sentence_transformers import SentenceTransformer

pull_request_nr = 2 # NOTE: Update this to the number of your pull request
model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_O3.onnx"},
    revision=f"refs/pr/{pull_request_nr}"
)
Once the pull request gets merged:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_O3.onnx"},
)
Only optimize once:
from sentence_transformers import SentenceTransformer, export_optimized_onnx_model

model = SentenceTransformer("path/to/my/mpnet-legal-finetuned", backend="onnx")
export_optimized_onnx_model(
    model=model, optimization_config="O3", model_name_or_path="path/to/my/mpnet-legal-finetuned"
)
After optimizing:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "path/to/my/mpnet-legal-finetuned",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_O3.onnx"},
)
Quantizing ONNX Models
ONNX models can be quantized to int8 precision using Optimum, allowing for faster inference on CPUs. To do this, you can use the export_dynamic_quantized_onnx_model() function, which saves the quantized in a directory or model repository that you specify. Dynamic quantization, unlike static quantization, does not require a calibration dataset. It expects:
model: a Sentence Transformer, Sparse Encoder, or Cross Encoder model loaded with the ONNX backend.quantization_config:"arm64","avx2","avx512", or"avx512_vnni"representing quantization configurations fromAutoQuantizationConfig, or anQuantizationConfiginstance.model_name_or_path: a path to save the quantized model file, or the repository name if you want to push it to the Hugging Face Hub.push_to_hub: (Optional) a boolean to push the quantized model to the Hugging Face Hub.create_pr: (Optional) a boolean to create a pull request when pushing to the Hugging Face Hub. Useful when you don’t have write access to the repository.file_suffix: (Optional) a string to append to the model name when saving it. If not specified,"qint8_quantized"will be used.
On my CPU, each of the default quantization configurations ("arm64", "avx2", "avx512", "avx512_vnni") resulted in roughly equivalent speedups.
See this example for quantizing a model to int8 with avx512_vnni:
Only quantize once:
from sentence_transformers import SentenceTransformer, export_dynamic_quantized_onnx_model

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="onnx")
export_dynamic_quantized_onnx_model(
    model=model,
    quantization_config="avx512_vnni",
    model_name_or_path="sentence-transformers/all-MiniLM-L6-v2",
    push_to_hub=True,
    create_pr=True,
)
Before the pull request gets merged:
from sentence_transformers import SentenceTransformer

pull_request_nr = 2 # NOTE: Update this to the number of your pull request
model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
    revision=f"refs/pr/{pull_request_nr}",
)
Once the pull request gets merged:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
)
Only quantize once:
from sentence_transformers import SentenceTransformer, export_dynamic_quantized_onnx_model

model = SentenceTransformer("path/to/my/mpnet-legal-finetuned", backend="onnx")
export_dynamic_quantized_onnx_model(
    model=model, quantization_config="avx512_vnni", model_name_or_path="path/to/my/mpnet-legal-finetuned"
)
After quantizing:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "path/to/my/mpnet-legal-finetuned",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
)
OpenVINO
OpenVINO allows for accelerated inference on CPUs by exporting the model to the OpenVINO format. To use the OpenVINO backend, you must install Sentence Transformers with the openvino extra:
pip install sentence-transformers[openvino]
To convert a model to OpenVINO format, you can use the following code:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="openvino")

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
If the model path or repository already contains a model in OpenVINO format, Sentence Transformers will automatically use it. Otherwise, it will convert the model to the OpenVINO format.
Note
If you wish to use the OpenVINO model outside of Sentence Transformers, you’ll need to perform pooling and/or normalization yourself. The OpenVINO export only converts the Transformer component, which outputs token embeddings, not sentence embeddings. To get sentence embeddings, you’ll need to apply the appropriate pooling strategy (like mean pooling) and any normalization that the original model uses.
model_kwargs will be passed on to OVBaseModel.from_pretrained(). Some notable arguments include:file_name: The name of the ONNX file to load. If not specified, will default to"openvino_model.xml"or otherwise"openvino/openvino_model.xml". This argument is useful for specifying optimized or quantized models.export: A boolean flag specifying whether the model will be exported. If not provided,exportwill be set toTrueif the model repository or directory does not already contain an OpenVINO model.
Tip
It’s heavily recommended to save the exported model to prevent having to re-export it every time you run your code. You can do this by calling model.save_pretrained() if your model was local:
model = SentenceTransformer("path/to/my/model", backend="openvino")
model.save_pretrained("path/to/my/model")
or with model.push_to_hub() if your model was from the Hugging Face Hub:
model = SentenceTransformer("intfloat/multilingual-e5-small", backend="openvino")
model.push_to_hub("intfloat/multilingual-e5-small", create_pr=True)
Quantizing OpenVINO Models
OpenVINO models can be quantized to int8 precision using Optimum Intel to speed up inference.
To do this, you can use the export_static_quantized_openvino_model() function,
which saves the quantized model in a directory or model repository that you specify.
Post-Training Static Quantization expects:
model: a Sentence Transformer, Sparse Encoder, or Cross Encoder model loaded with the OpenVINO backend.quantization_config: (Optional) The quantization configuration. This parameter accepts either:Nonefor the default 8-bit quantization, a dictionary representing quantization configurations, or anOVQuantizationConfiginstance.model_name_or_path: a path to save the quantized model file, or the repository name if you want to push it to the Hugging Face Hub.dataset_name: (Optional) The name of the dataset to load for calibration. If not specified, defaults tosst2subset from thegluedataset.dataset_config_name: (Optional) The specific configuration of the dataset to load.dataset_split: (Optional) The split of the dataset to load (e.g., ‘train’, ‘test’).column_name: (Optional) The column name in the dataset to use for calibration.push_to_hub: (Optional) a boolean to push the quantized model to the Hugging Face Hub.create_pr: (Optional) a boolean to create a pull request when pushing to the Hugging Face Hub. Useful when you don’t have write access to the repository.file_suffix: (Optional) a string to append to the model name when saving it. If not specified,"qint8_quantized"will be used.
See this example for quantizing a model to int8 with static quantization:
Only quantize once:
from sentence_transformers import SentenceTransformer, export_static_quantized_openvino_model

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="openvino")
export_static_quantized_openvino_model(
    model=model,
    quantization_config=None,
    model_name_or_path="sentence-transformers/all-MiniLM-L6-v2",
    push_to_hub=True,
    create_pr=True,
)
Before the pull request gets merged:
from sentence_transformers import SentenceTransformer

pull_request_nr = 2 # NOTE: Update this to the number of your pull request
model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="openvino",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
    revision=f"refs/pr/{pull_request_nr}"
)
Once the pull request gets merged:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="openvino",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
)
Only quantize once:
from sentence_transformers import SentenceTransformer, export_static_quantized_openvino_model
from optimum.intel import OVQuantizationConfig

model = SentenceTransformer("path/to/my/mpnet-legal-finetuned", backend="openvino")
quantization_config = OVQuantizationConfig()
export_static_quantized_openvino_model(
    model=model, quantization_config=quantization_config, model_name_or_path="path/to/my/mpnet-legal-finetuned"
)
After quantizing:
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "path/to/my/mpnet-legal-finetuned",
    backend="openvino",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
)
Benchmarks
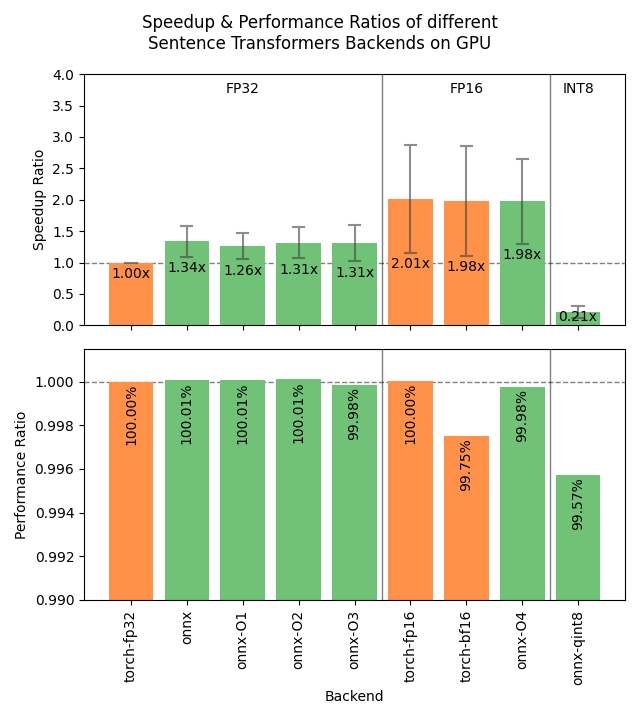
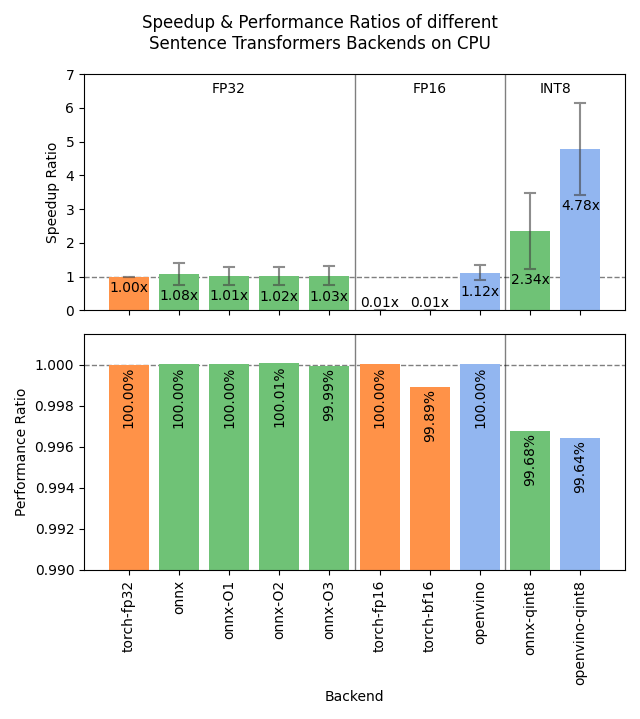
The best backend depends on your hardware, model and input lengths. The figures below compare throughput across several models and datasets, using PyTorch FP32 as the baseline. Alongside the median speedup, they show the average task-quality ratio so you can see whether a faster configuration affects embedding quality.
Expand the benchmark details
I measured GPU throughput on an RTX 3090 and CPU throughput on an i7-13700K. Each speedup compares a backend with the matching model and workload in PyTorch FP32, and the bars summarize these ratios across the tested combinations. The whiskers show variation between combinations, rather than confidence intervals. The GPU llama.cpp measurements use their own matching FP32 baseline.
Datasets: the workloads range from short sentences to long reviews:
sentence-transformers/stsb: 38.9 characters on average (SD=13.9)
sentence-transformers/natural-questions: answers only, 619.6 characters on average (SD=345.3)
stanfordnlp/imdb: texts repeated 4 times, 9589.3 characters on average (SD=633.4)
Models:
sentence-transformers/all-MiniLM-L6-v2: 22.7M parameters.
BAAI/bge-base-en-v1.5: 109M parameters.
mixedbread-ai/mxbai-embed-large-v1: 335M parameters.
BAAI/bge-m3: 567M parameters (GPU only).
The GPU Sentence Transformers and ONNX tests use 2,000 samples per dataset. The CPU tests use 1,000 samples for MiniLM and BGE-base and 512 for mxbai-large. Mxbai-large is tested only on short sentences and NQ answers, giving eight CPU model and workload combinations in total.
The throughput comparison uses each backend’s best tested batch size. On CPU, each model and backend used its best-performing setting from 8 and 20 threads. ONNX Runtime’s intra-op thread count was set explicitly, with inter-op set to 1.
After warmup, CPU timings use either the median of five passes or the mean of two passes. The CPU torch-fp16 and torch-bf16 results come from smaller checks on 128 samples, using the FP32-selected settings and two timed passes against matching FP32 controls.
The ranking changes on Hugging Face Jobs cpu-upgrade instances, where llama.cpp leads instead of OpenVINO INT8. The cloud figure covers six model and workload combinations, with speedups relative to PyTorch FP32 on that CPU:
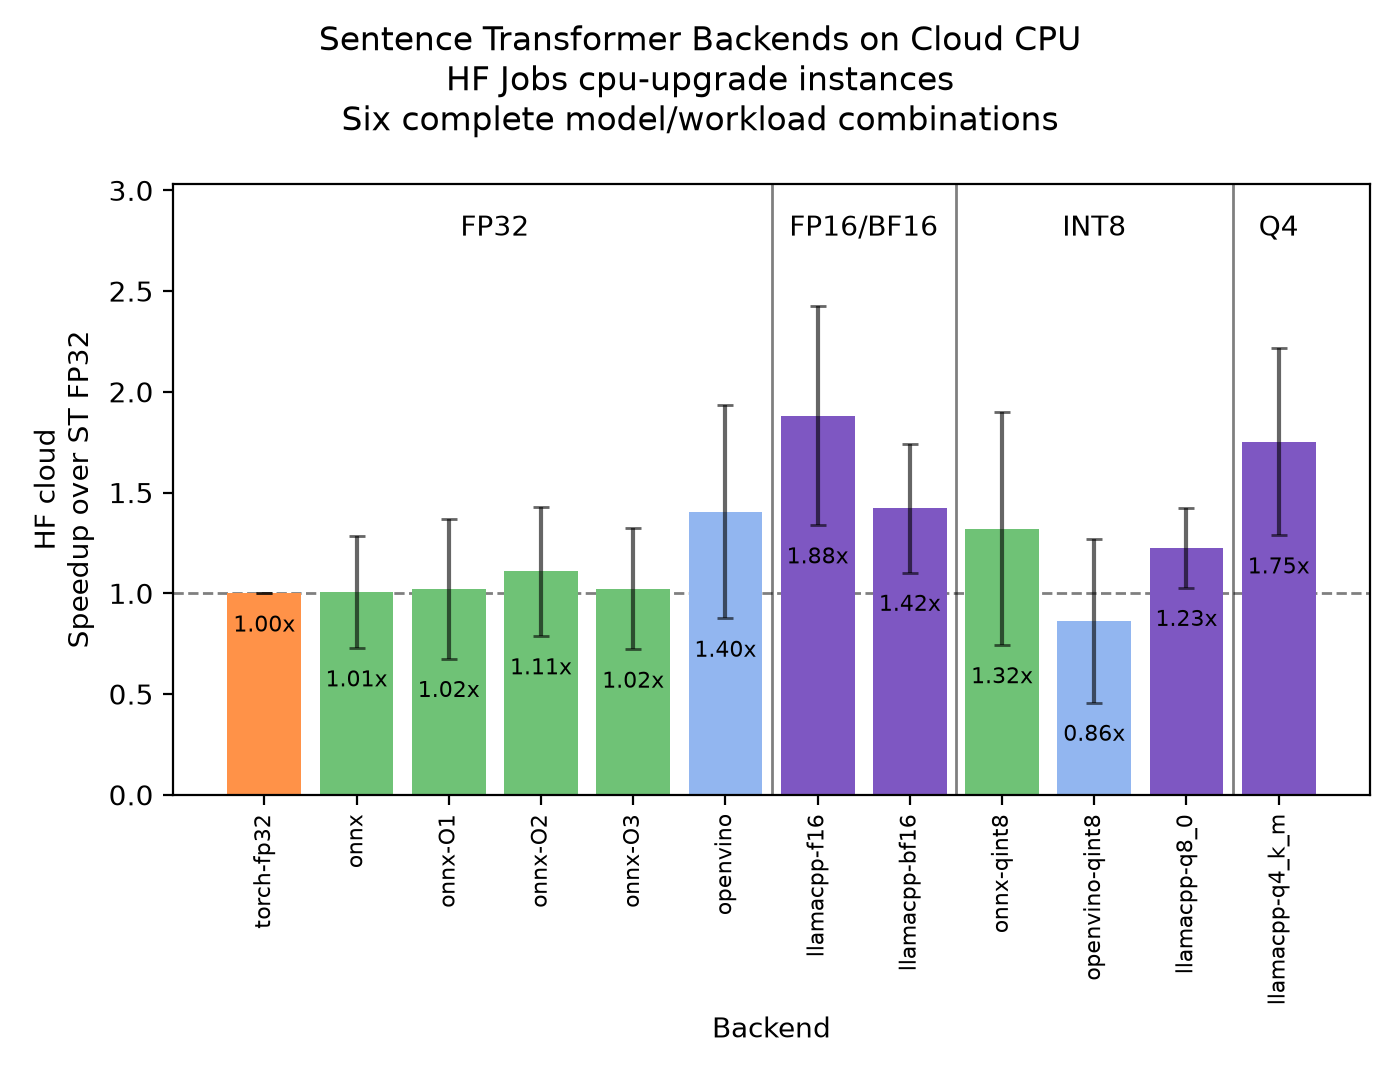
For quality, each configuration’s task scores are compared with PyTorch FP32 and the resulting ratios are averaged. The evaluation covers both sentence similarity and retrieval to capture different uses of the embeddings:
Semantic Textual Similarity: Spearman rank correlation based on cosine similarity on the sentence-transformers/stsb test set, computed via the EmbeddingSimilarityEvaluator.
Information Retrieval: NDCG@10 based on cosine similarity on the entire NanoBEIR collection of datasets, computed via the InformationRetrievalEvaluator.
The CPU quality bars cover both tasks for MiniLM, BGE-base and mxbai-large, giving six ratios per backend. Quality evaluations use matching model artifacts on CPU or GPU, with OpenVINO and ONNX INT8 evaluated on CPU. The CPU torch-fp16 and torch-bf16 quality bars use GPU scores relative to matching GPU FP32 scores.
For llama.cpp in the GPU figure, quality is evaluated on MiniLM and BGE-base, while throughput also covers mxbai-large and BGE-M3. BGE-M3 Q4 is excluded because its embeddings failed the agreement check against FP32.
Backends:
torch-fp32: PyTorch with float32 precision (default).torch-fp16: PyTorch with float16 precision, viamodel_kwargs={"torch_dtype": "float16"}.torch-bf16: PyTorch with bfloat16 precision, viamodel_kwargs={"torch_dtype": "bfloat16"}.torch-fp16-fa2: PyTorch with float16 precision and FlashAttention-2 with automatic input unpadding, viamodel_kwargs={"torch_dtype": "float16", "attn_implementation": "flash_attention_2"}.torch-bf16-fa2: the same with bfloat16 precision.onnx: ONNX with float32 precision, viabackend="onnx".onnx-O1: ONNX with float32 precision and O1 optimization, viaexport_optimized_onnx_model(..., optimization_config="O1", ...)andbackend="onnx".onnx-O2: ONNX with float32 precision and O2 optimization, viaexport_optimized_onnx_model(..., optimization_config="O2", ...)andbackend="onnx".onnx-O3: ONNX with float32 precision and O3 optimization, viaexport_optimized_onnx_model(..., optimization_config="O3", ...)andbackend="onnx".onnx-O4: ONNX with float16 precision and O4 optimization, viaexport_optimized_onnx_model(..., optimization_config="O4", ...)andbackend="onnx".onnx-qint8: ONNX quantized to int8 with “avx512_vnni”, viaexport_dynamic_quantized_onnx_model(..., quantization_config="avx512_vnni", ...)andbackend="onnx". The different quantization configurations resulted in roughly equivalent speedups.openvino: OpenVINO, viabackend="openvino".openvino-qint8: OpenVINO quantized to int8 viaexport_static_quantized_openvino_model(..., quantization_config=OVQuantizationConfig(), ...)andbackend="openvino".llamacpp-*: native llama.cpp with GGUF models in F16, BF16, Q8_0 or Q4_K_M format.
Half precision provides a substantial speedup on these models: plain FP16 reaches a median 2.92x the throughput of FP32. Combining it with Flash Attention 2 and input unpadding raises that to 3.87x, with BF16 performing similarly at 3.84x. This makes half precision with Flash Attention a useful starting point when your model supports it.
OpenVINO INT8 performs best on the local i7-13700K shown here, but llama.cpp leads on the cloud instance I tested. It’s worth testing backends on your deployment hardware, with inputs representative of your application.
Sentence Transformers performed best on the smaller GPU models I tested, while llama.cpp became competitive on 8B models. CPU rankings differed between my local machine and the cloud instance, so benchmark on your deployment hardware.
Compare with llama.cpp
The aggregate results above cover models up to BGE-M3. To explore how the comparison changes with larger models and different input lengths, I also compared Sentence Transformers with native llama.cpp on models up to Qwen3-Embedding-8B. These measurements use an RTX 3090 with 24 GB of VRAM under WSL2, with batch sizes tuned for each backend.
The charts show median throughput, with whiskers indicating the interquartile range across repeated measurements. For Sentence Transformers, they compare the default unpadded FA2 configuration with padding enabled. Unpadding is automatic for text-only inputs when the Flash Attention implementation and model architecture support it. For llama.cpp, the GPU-table bars move the input embedding table from its default placement in CPU memory to CUDA.
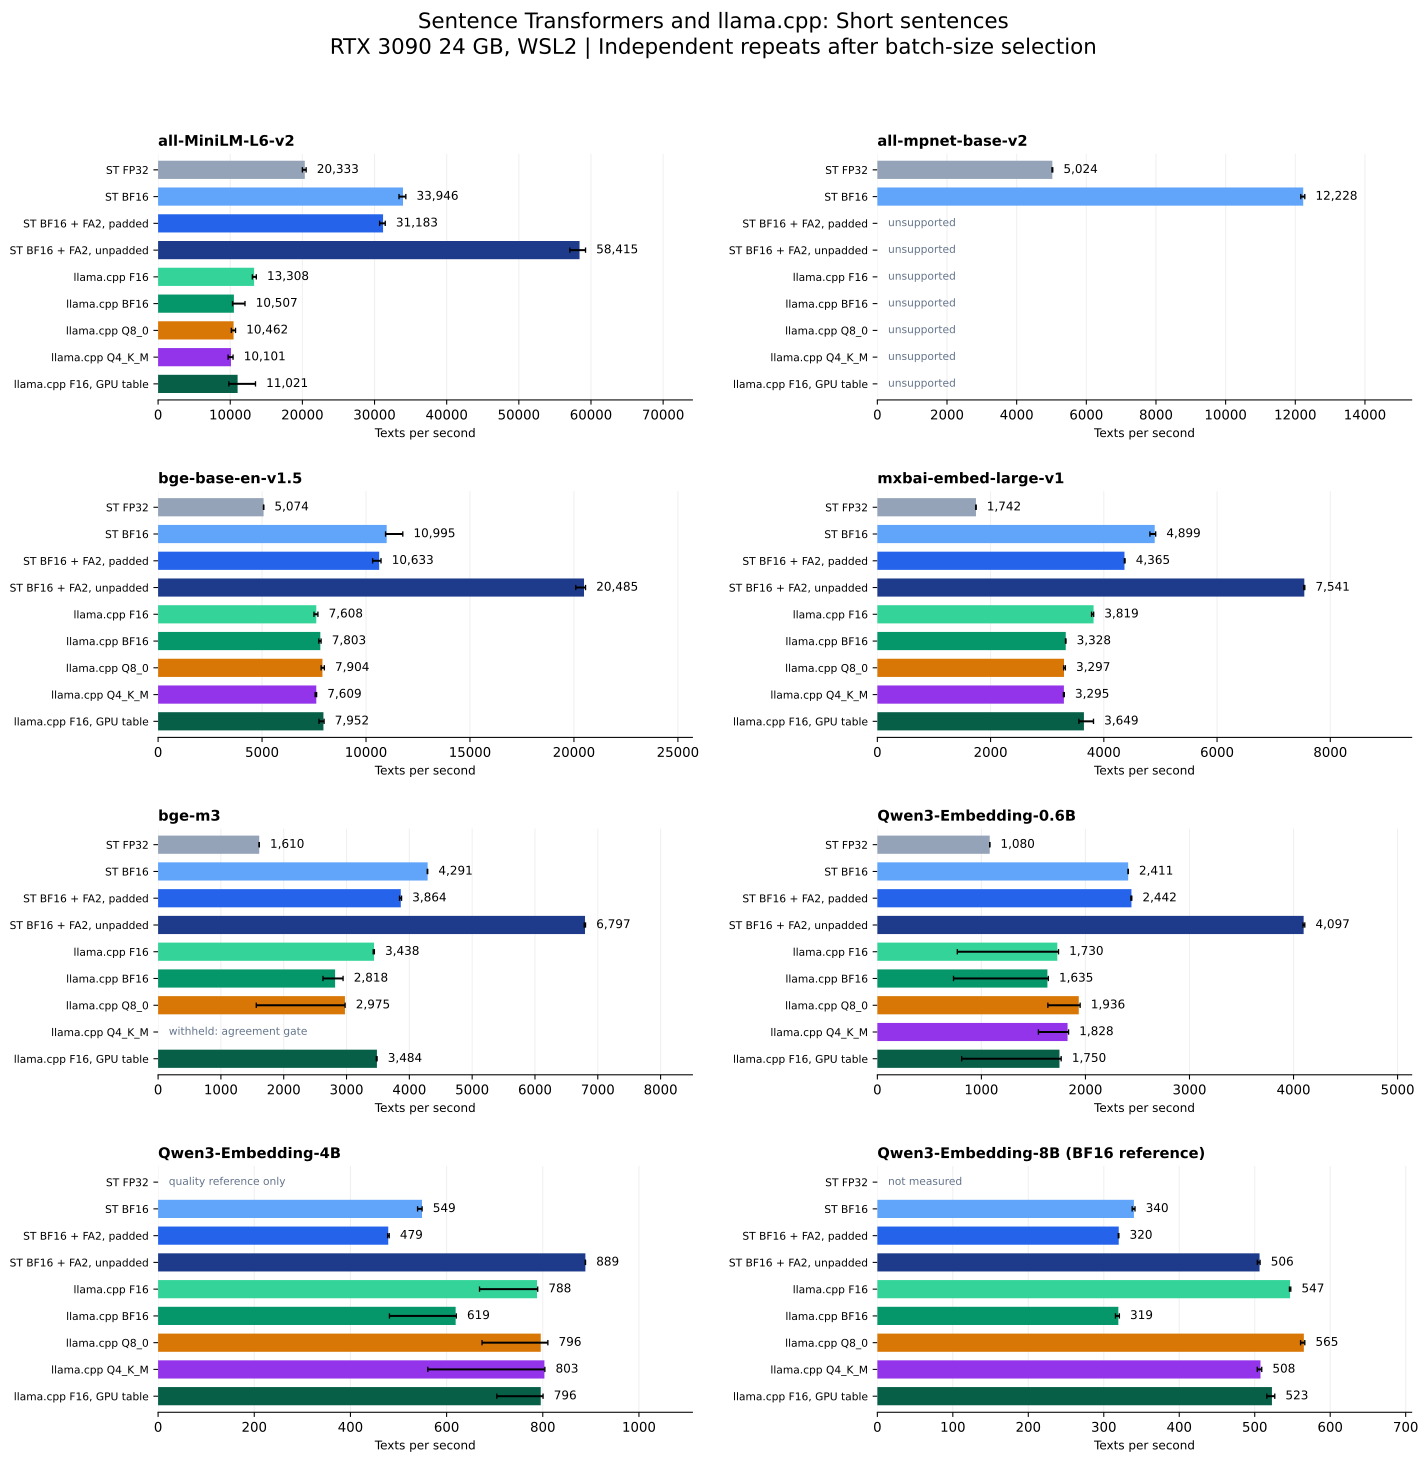
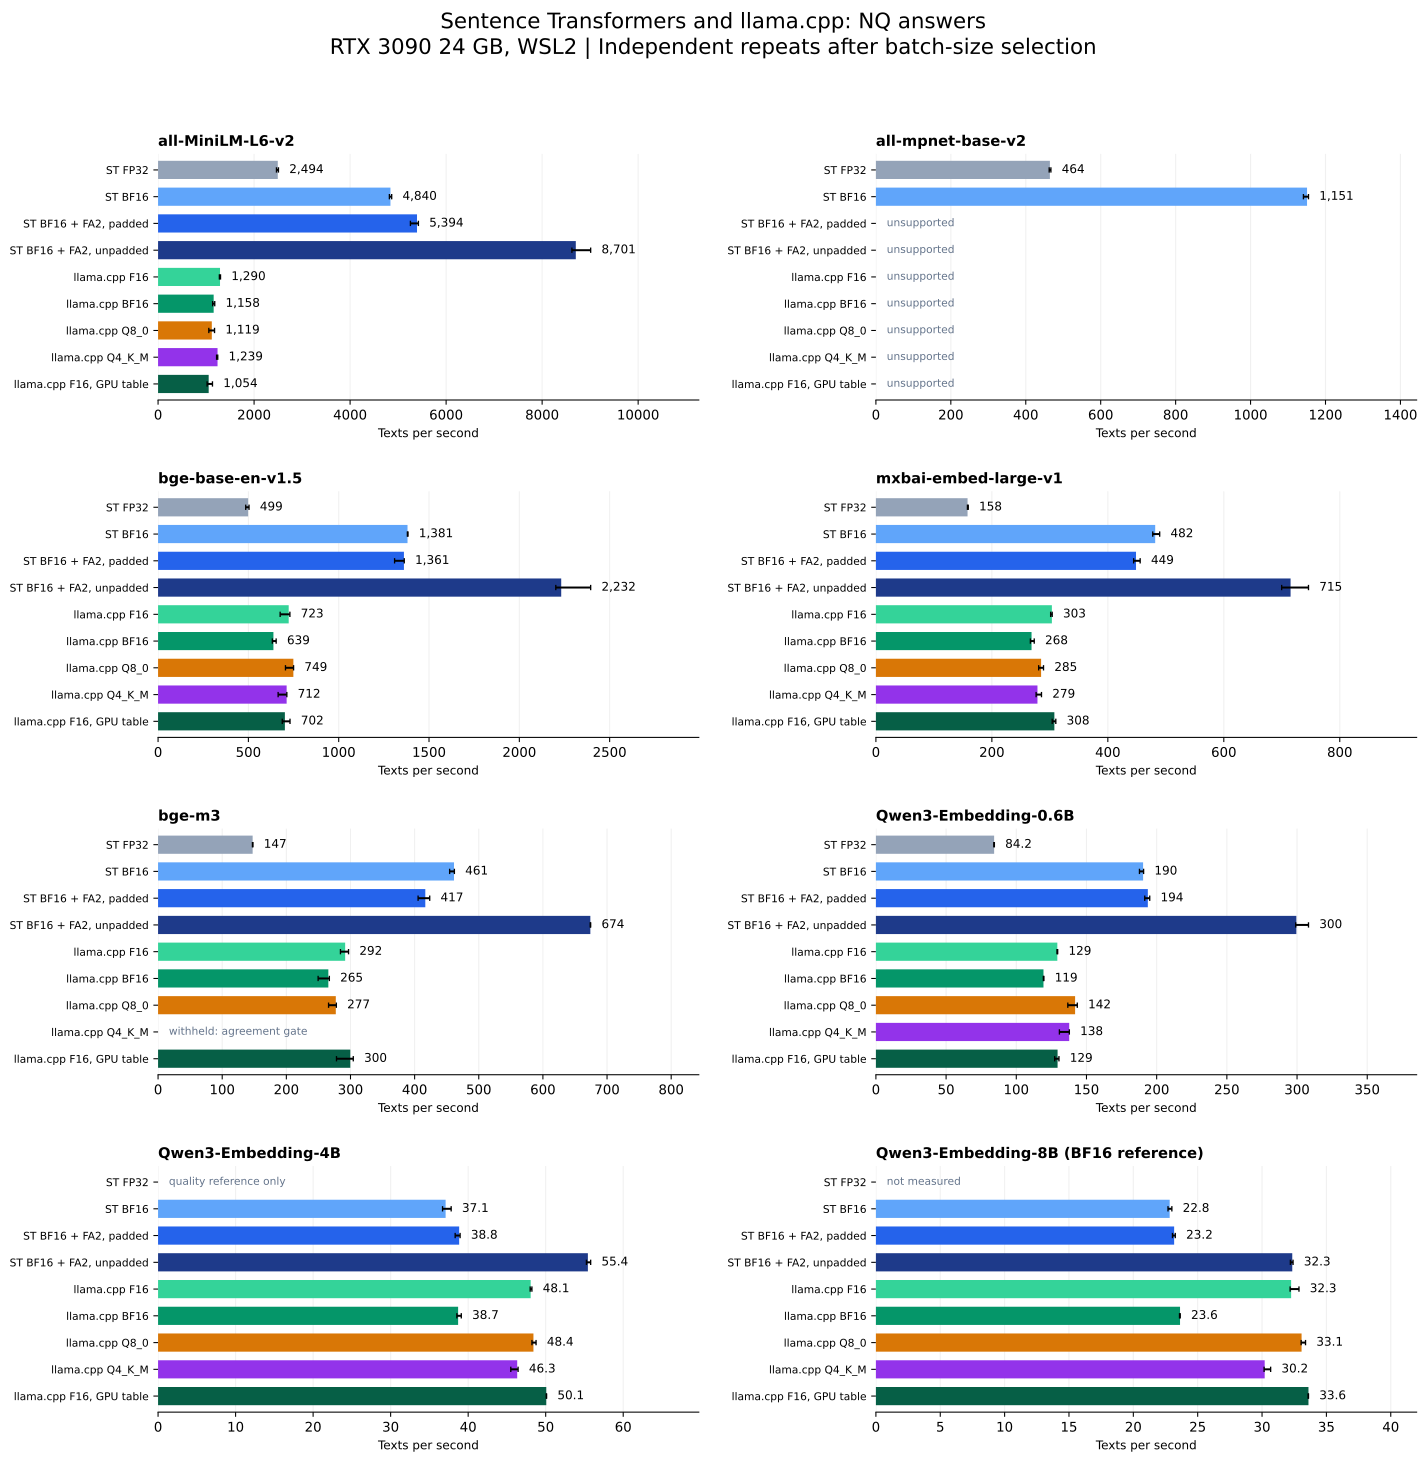
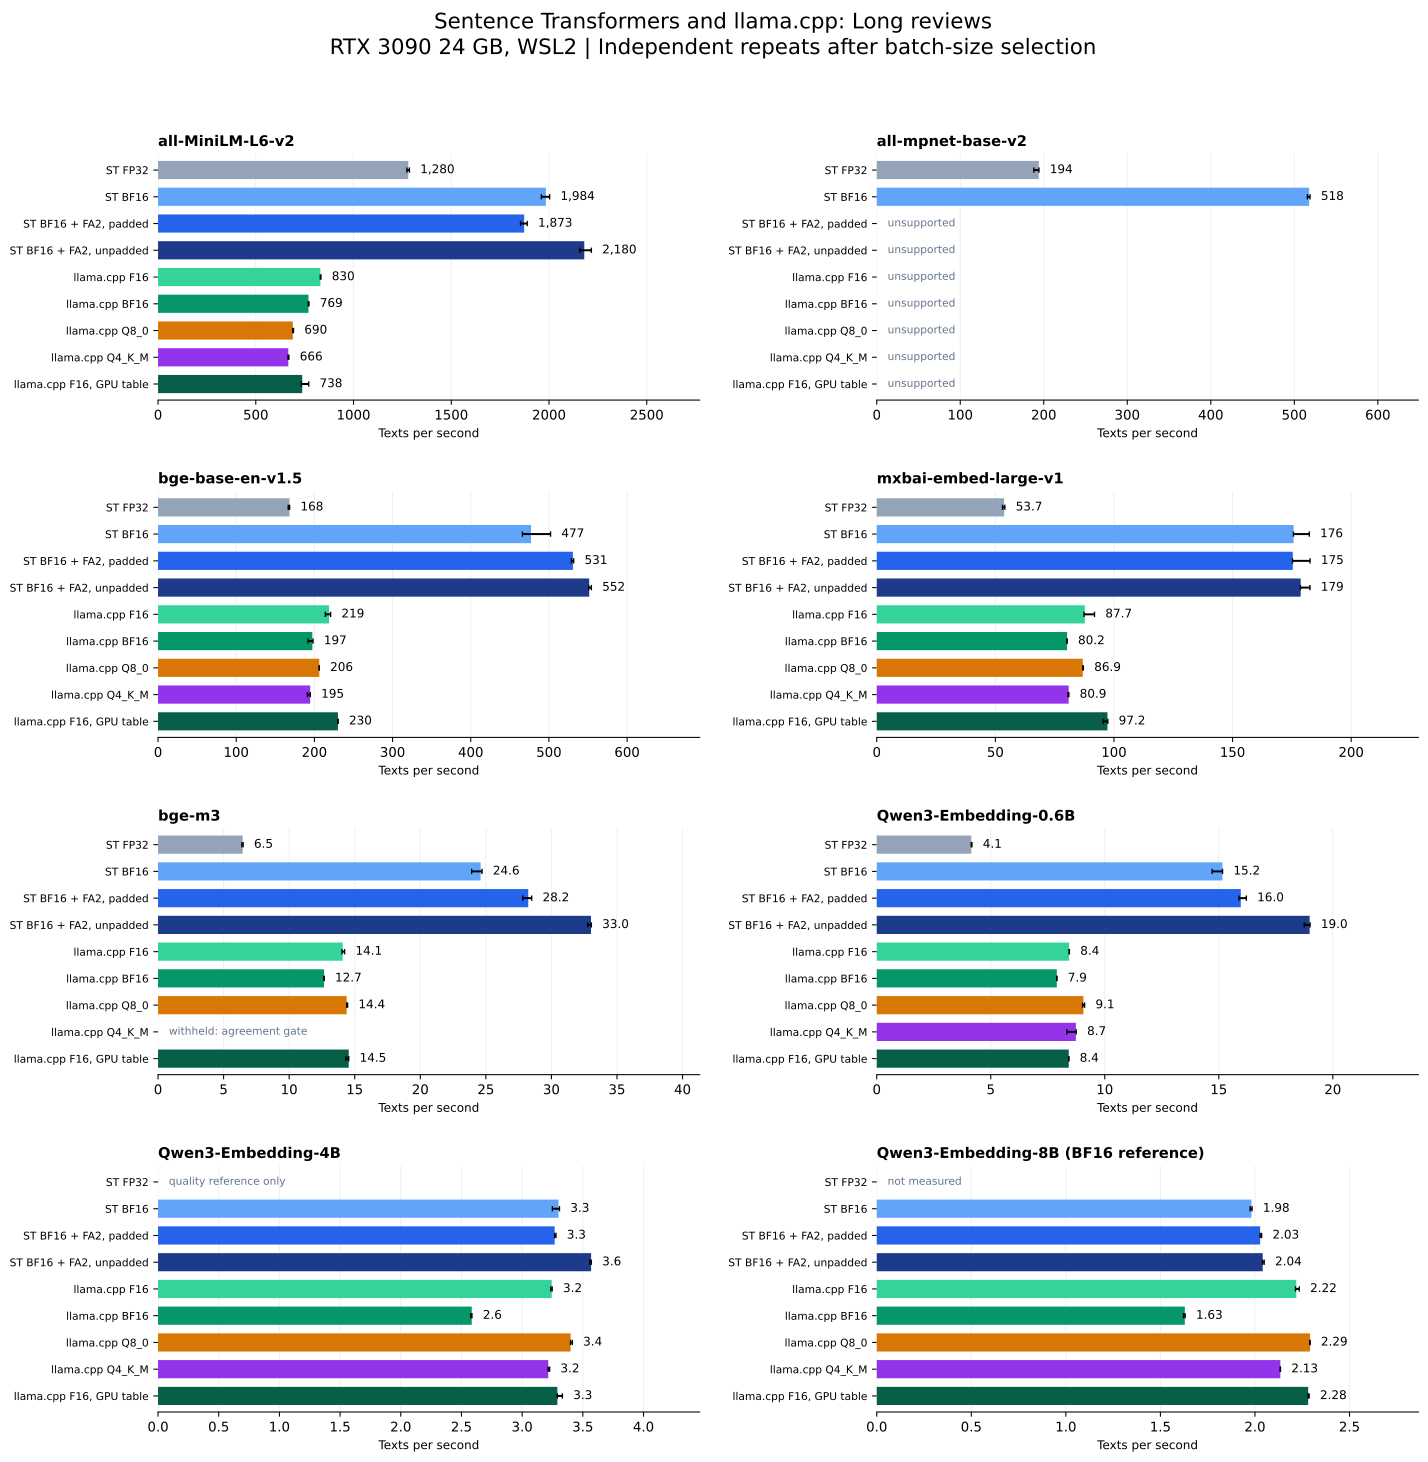
Sentence Transformers with BF16, Flash Attention 2 and unpadding leads on the small models, running 2.6 to 6.7 times faster than the fastest tested llama.cpp configuration on MiniLM and 2.4 to 3.0 times faster on BGE-base. The gap is much smaller on Qwen3-Embedding-4B, where the same configuration leads by about 5 to 11 percent.
On Qwen3-Embedding-8B, the comparison shifts in favor of llama.cpp: Q8_0 with default embedding-table placement is about 12%, 2% and 12% faster than Sentence Transformers with BF16, FA2 and unpadding on short sentences, NQ answers and long reviews, respectively. More aggressive quantization does not help here, as Q4 is slower than Q8 on all three workloads. These results make llama.cpp worth considering for larger models, particularly when quantization helps them fit in memory, although models above 8B were not tested.
Note
These results measure throughput with tuned batches, so the best configuration for single-request latency may differ. The comparison also checks embedding agreement rather than fully evaluating retrieval quality. Test both speed and task quality on representative inputs before choosing a backend.
Timings for Sentence Transformers and native llama.cpp include tokenization, model execution, pooling, normalization and returning embeddings to CPU memory. The benchmark calls llama.cpp directly, so its timings do not include HTTP transport.
To compare each model on the same workload, both backends use identical inputs and matching truncation limits: 256 tokens for MiniLM, 384 for MPNet, 512 for BGE-base and mxbai-large, 8,192 for BGE-M3, 32,768 for Qwen 0.6B and 40,960 for Qwen 4B and 8B. The workloads contain 2,000 short sentences, 1,000 NQ answers and 256 long reviews (repeated text). Qwen 4B and 8B use prefixes of 1,024, 256 and 64 texts.
I checked embedding agreement on 552 texts against FP32, using BF16 as the reference for 8B. Configurations that fail this check are marked as withheld, including BGE-M3 Q4. MPNet has no supported FA2 or llama.cpp implementation in the tested versions, so those configurations are marked as unsupported.
Sentence Transformers uses the same checkpoints as the llama.cpp GGUF conversions, which are tested in F16, BF16, Q8_0 and Q4_K_M. Decoder models use model[0].config.use_cache = False to avoid retaining a generation cache during embedding inference. The llama.cpp GPU-table variants reuse the default F16 token budgets.
The software versions are Sentence Transformers 6.1.0.dev0 (084d9f7183b7), PyTorch 2.11.0+cu128, Transformers 5.14.1 and kernels 0.15.2 with kernels-community/flash-attn2. llama.cpp uses revision 4d91760, built with CUDA.
Recommendations
Based on the benchmarks, this flowchart should help you decide which backend to use for your model:
        %%{init: {
   "theme": "neutral",
   "flowchart": {
      "curve": "bumpY"
   }
}}%%
graph TD
A("What is your hardware?") -->|GPU| B("Does your model support<br>Flash Attention?")
A -->|CPU| C("Is a small accuracy loss<br>acceptable?")
B -->|yes| K["float16 + Flash Attention"]
B -->|no| F[float16]
C -->|yes| G[openvino-qint8]
C -->|no| H("Do you have an Intel CPU?")
H -->|yes| I[openvino]
H -->|no| J[onnx]
click K "#pytorch"
click F "#pytorch"
click G "#quantizing-openvino-models"
click I "#openvino"
click J "#onnx"
Note
Your mileage may vary, and you should always test the different backends with your specific model and data to find the best one for your use case.
User Interface
This Hugging Face Space provides a user interface for exporting, optimizing, and quantizing models for either ONNX or OpenVINO: