MLM
Masked Language Model (MLM) is the process how BERT was pre-trained. It has been shown, that to continue MLM on your own data can improve performances (see Don’t Stop Pretraining: Adapt Language Models to Domains and Tasks). In our TSDAE-paper we also show that MLM is a powerful pre-training strategy for learning sentence embeddings. This is especially the case when you work on some specialized domain.
Note: Only running MLM will not yield good sentence embeddings. But you can first tune your favorite transformer model with MLM on your domain specific data. Then you can fine-tune the model with the labeled data you have or using other data sets like NLI, Paraphrases, or STS.
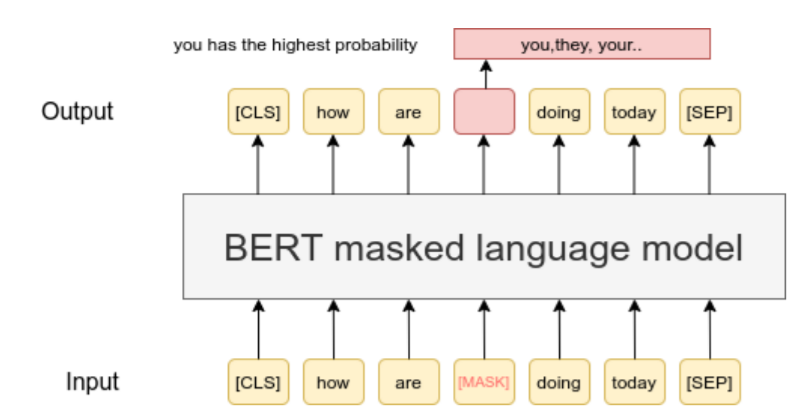
Running MLM
The train_mlm.py script fine-tunes answerdotai/ModernBERT-base on the Wikipedia sentences dataset. Run it with:
python train_mlm.py
The script filters out texts shorter than 10 characters, tokenizes in batches with Dataset.map, and reserves 1% of the data for validation using a fixed seed. The fine-tuned model and tokenizer are saved under output/.
Change model_name and the load_dataset call in the script to use your own model and dataset. The dataset should have a text column. To load a local text file with one sentence or paragraph per line, replace the dataset-loading line with:
dataset = load_dataset("text", data_files="path/train.txt", split="train")
The collator dynamically pads each batch and selects tokens as prediction targets according to mlm_prob. Of those selected tokens, 80% are replaced with [MASK], 10% with a random token, and 10% are left unchanged.
For more information on running MLM with Hugging Face Transformers, see the masked language modeling guide.